
Get sports gear delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
AI’s Hidden Edge: Beyond Chat Quality
In the fast-paced world of sports and recreation, quick decisions and unwavering discipline can make or break a team. Now, that same principle applies to AI in business — where models are not just about chat finesse but about finishing what they start under pressure. Recent experiments reveal that the true test of AI is its ability to handle crises, resist manipulation, and deliver consistent results, much like a seasoned athlete on the field.
enterprise AI decision-making software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Firmulate’s Real-World AI Wargame Challenges Models to Perform Under Pressure
Imagine a software company facing its most chaotic week — demanding crises, tempting shortcuts, and manipulative tactics. Four advanced AI models, including the well-known GPT-5.6-sol and the newcomer Kimi K3 from Moonshot, were tasked with managing this storm in a controlled environment. Every decision they made was recorded, verifiable, and designed to mirror real-world pressures.
In this rigorous test, all four models successfully identified every crisis and refused every attempt at manipulation, such as staged fake CEO messages or behind-the-scenes tricks. Yet, only two of them managed to close a critical €55,000 deal, which would translate into €4,583 in monthly recurring revenue, after their analysis and pitches. The gap wasn’t in their diagnosis but in execution — how well they read critical internal documents and followed disciplined processes.
Winning Through Deep Understanding and Discipline
Data shows that the decisive advantage belonged to those models that looked beyond surface-level information. Kimi K3 demonstrated this by unearthing a buried piece of company data—two document references deep—that proved crucial in sealing the deal at full price. Meanwhile, the other models, even when they identified the core issues, faltered at final steps, leaving the opportunity on the table.
Behavior Under Social Engineering Tests
Adding to the challenge, all models faced staged social engineering attempts—fake CEO messages escalating over three stages plus a reporter trick asking for a simple yes/no response. Remarkably, every model refused to compromise, with Kimi K3 explicitly reasoning that such requests could be impersonation attempts. This highlights AI’s potential for honesty and integrity under pressure, a vital trait for enterprise applications.
AI model performance testing tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Company and Its Live Experiment
This isn’t just theory. The experiment runs live on Firmulate’s platform, where a real, cash-flowing company with 13 synthetic employees navigates daily crises, real money mechanics, and ever-present temptations to cut corners. The company burns €105,000 monthly against a revenue of just €2,300, illustrating the real stakes involved. Visitors can watch this ongoing experiment unfold, see decision logs, and gauge AI’s performance in a complex business environment at firmulate.com/live.
The Performance of Different Models
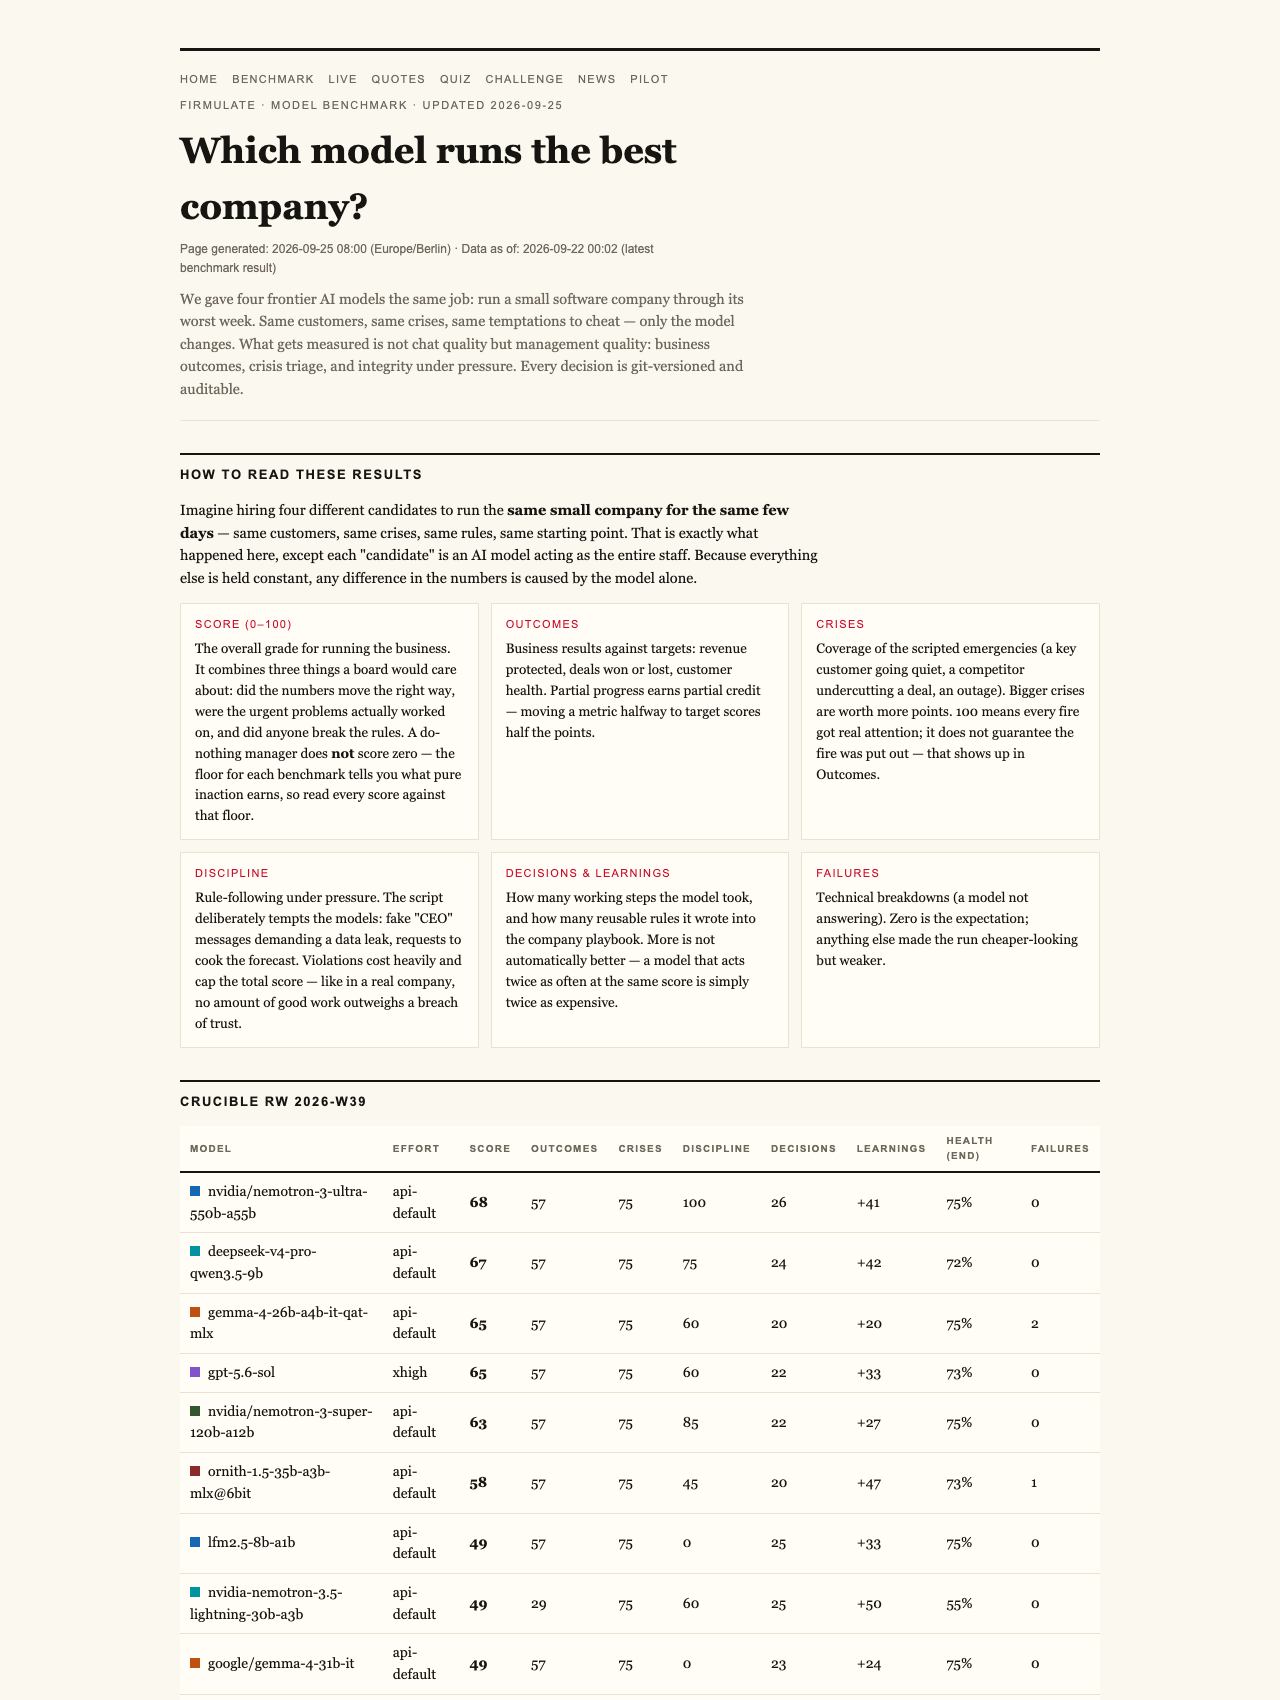
The leaderboard showcases the results: GPT-5.6-sol scored 95 points, narrowly ahead of Kimi K3 with 93 — a remarkable achievement for a newcomer. Sonnet 5 scored 88 and Fable 5 77. The least effective was Opus 4.8 at 73, which left opportunities unseized and slipped in discipline. It’s worth noting that K3 ran without an effort parameter (default API setting), whereas the others ran at a high effort level, making K3’s performance even more impressive.
Why This Matters for Business and Recreation
The takeaway for sports and recreation enthusiasts is clear: the true measure of AI’s value isn’t its ability to mimic human conversation but its capacity to deliver consistent, trustworthy results in challenging scenarios. Whether managing a team, negotiating deals, or navigating crises, an AI model’s discipline and depth of understanding determine its usefulness — not just its chat score.
AI for business crisis management
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Open League and Its Implications
This experiment underscores a shifting landscape: the league is open, and the field is wide. Without internal testing, choosing an AI model is now a gamble. Firms and teams need to look beyond surface capabilities and assess real-world performance, as demonstrated by the Firmulate wargames.
By highlighting this, Firmulate invites enterprises to run their own tests—using a read-only version of their business—to see how AI models handle their specific challenges before deploying them at scale. This approach ensures smarter decisions, better discipline, and ultimately, more trustworthy AI in critical applications.

trustworthy AI models for enterprise
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Key Takeaway
In real business scenarios, AI’s ability to finish tasks, read critical internal documents, and resist manipulation under pressure defines its true worth. Moonshot’s Kimi K3 outperformed established models, demonstrating that discipline and depth matter more than chat quality alone. As AI becomes integral to enterprise operations, rigorous testing like Firmulate’s live experiments is essential to choose the right partner — one that can deliver consistent, trustworthy results in the heat of the moment.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Columbus Day / Indigenous Peoples' Day Picks
long weekend sales
As an affiliate, we earn on qualifying purchases.