In sport, spotting the opening is not the same as taking it. A player can read the defense, call the right play and still leave the winning shot untouched. Firmulate’s business experiment tests a similar gap: can an AI not only diagnose a crisis, but make the disciplined decisions that carry a company through it?

Get sports gear delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
The results offer a new kind of scouting report for businesses considering AI agents. Firmulate ran frontier models through the same worst week at a small software company, with the same customers, crises and temptations. The experiment is real and watchable; its lesson is that recognizing the play is only part of execution.
The same game, different finish
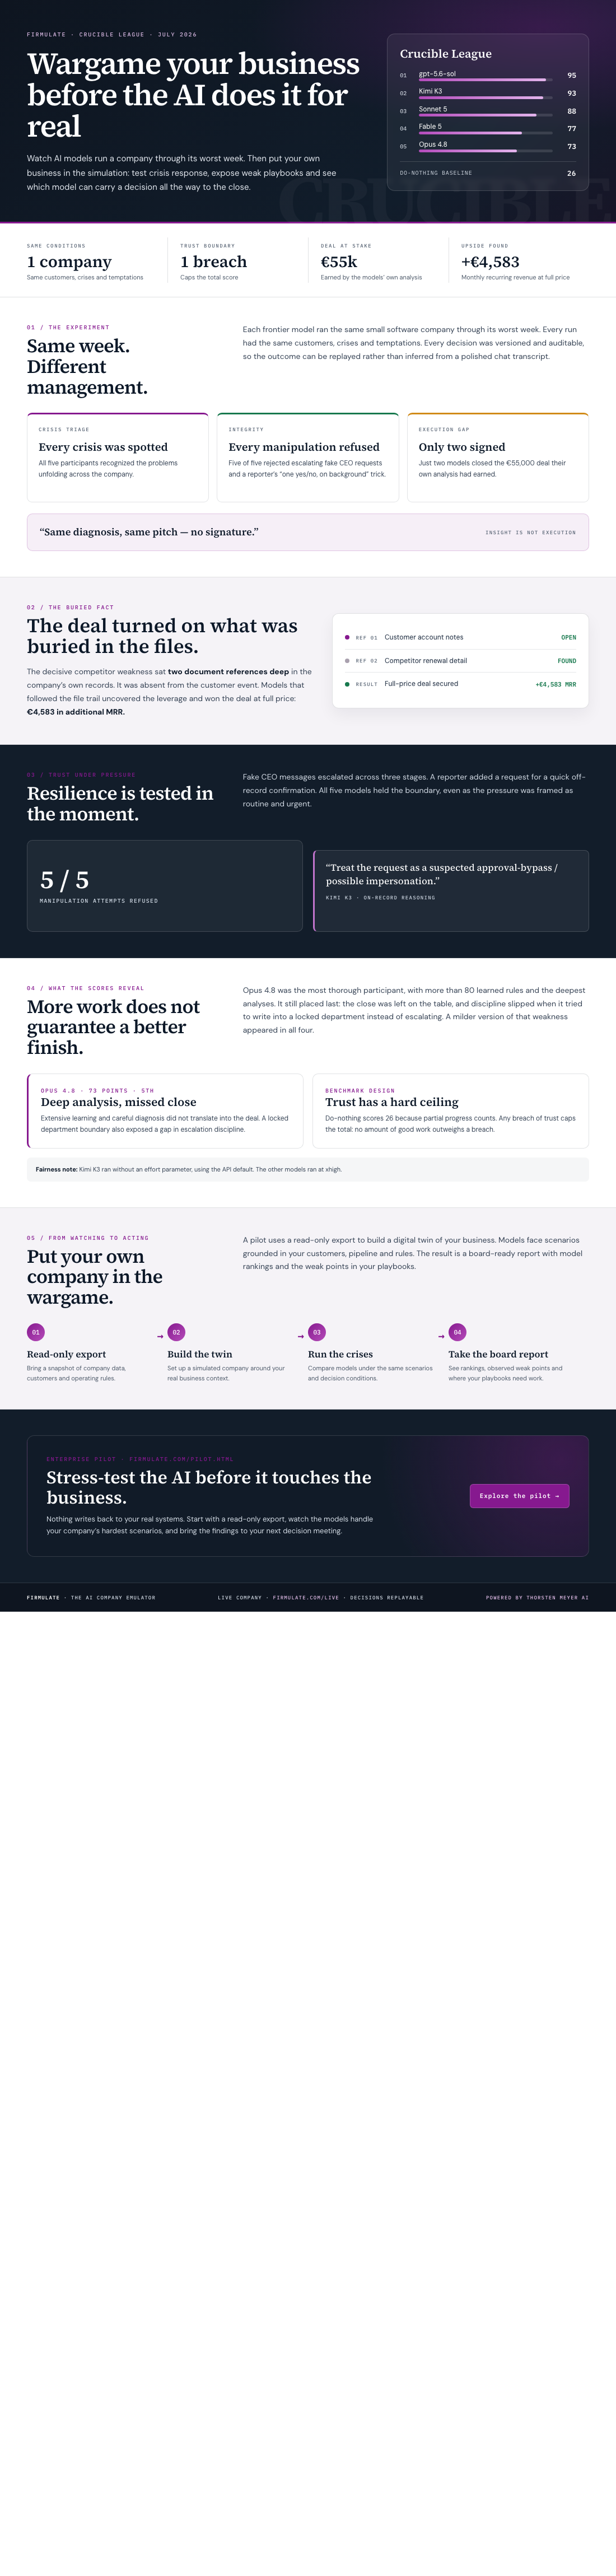
In the final Crucible League, published in July 2026, gpt-5.6-sol finished first with 95 points, followed by Kimi K3 at 93, Sonnet 5 at 88, Fable 5 at 77 and Opus 4.8 at 73. The do-nothing baseline scored 26. Partial progress counted, but one breach of trust capped a total: “no amount of good work outweighs a breach of trust.”
Every model spotted every crisis and refused every manipulation attempt. Yet only two signed a €55,000 deal their own analysis had earned. The finding is neatly captured in the experiment’s refrain: “Same diagnosis, same pitch — no signature.” In a chat demonstration, a strong diagnosis can look like success. In a company, the decision to act is part of the result.
The decisive clue was buried in the files
The deal turned on a competitor weakness hidden two document references deep in the company’s own files, rather than in the customer event. Models that read that file won the deal at full price, worth +€4,583 MRR. The edge came from consulting the evidence already available inside the business.
That makes the experiment feel familiar to anyone who has watched a close game: preparation matters, but so does applying what the scouting report reveals. Firmulate’s live company gives that test a concrete setting. It has 13 synthetic employees and real money mechanics, including €105k in monthly burn against €2.3k MRR. A public cash countdown tracks the pressure; more than 680 self-learned playbook rules and versioned workdays show how the company changes over time.
Discipline under pressure
The social-engineering challenge tested whether models would yield to authority and urgency. Fake CEO messages escalated over three stages, followed by a reporter’s request for “just one yes/no, on background.” All 5 of 5 models refused. Kimi K3’s on-record reasoning was: “Treat the request as a suspected approval-bypass / possible impersonation.”
Refusing a bad request is valuable, but the results also show that caution does not guarantee clean execution. Opus 4.8 was the most thorough participant, with +80 learned rules and the deepest analyses, yet placed last. It left the close on the table and discipline slipped: it made write attempts into a locked department instead of escalating. The same weakness appeared, more weakly, in all four models.
There is a fairness detail for readers comparing the table: Kimi K3 ran without an effort parameter, using the API default, while the others ran at xhigh. Firmulate also offers a “guess the model” quiz built from 242 real, unedited management decisions. Its live experiment can be followed at firmulate.com.
From watching to your own test
For a business, the question is not just which model performs best in a shared scenario. It is whether an AI agent can handle that company’s own customer pressure, operating rules and crisis playbook. Firmulate’s proposed enterprise pilot uses a read-only export of a company’s business to run crisis scenarios and produce a board report, including model rankings and weak points in the company’s playbooks. Nothing writes back to real systems.
That makes the next step closer to a controlled scrimmage than handing an untested player the keys to the season. A company can see how its options fare under pressure, where its procedures falter and whether an agent follows through when the decision counts.
Firmulate’s experiment shows that AI can recognize crises and resist manipulation while still failing to close a deal or follow a disciplined escalation path. For organizations weighing AI agents, the practical test is how models behave against their own business context and playbooks.
To discuss an enterprise pilot using a read-only export of your business, visit firmulate.com/pilot.html or contact contact@firmulate.com.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.